
How to Use Reddit to Get AI Mentions in 2026 (A 2-Upvote Comment Did It)
Short version: a two-year-old Reddit thread, with a two-upvote comment in it, is one of the four sources Perplexity read before recommending a competitor of mine for a prompt I track. Nobody paid for that placement and nobody ran a campaign. One person answered a question in r/content_marketing in 2024, and an AI assistant has been reading the answer ever since.
This article is the method I use to find threads like that for my own prompts, what the evidence does and doesn't prove about Reddit's influence on AI answers, and how to show up in those threads without getting banned. The screens are from my own brand monitor and from live Perplexity and ChatGPT sessions recorded in mid-July 2026, so every number is date-stamped to then.
Step 1: write down the prompts, not the keywords
Everything starts with a list of 10 to 15 prompts you want your brand named for. You don't need a tool for this part. You know what your buyers ask better than any keyword database does, and a prompt is just a longer-tailed keyword with a conversation attached. "Best CRM software for dentists" is a keyword. "What's the best software for a dentist CRM, and find me one with a 50% discount that's local to LA" is the same intent after two turns of a chat.
Two things about that conversation matter for Reddit specifically. First, the assistant decides what kind of answer satisfies the intent, the same way Google shows short videos for "how to tie a tie" and a map pack for "Indian restaurant Dallas". For a "which tool should I use" prompt, the answer is a shortlist, and shortlists get built from pages that already contain shortlists: listicles, comparison tables, and threads where people recommend things to each other. Second, the brands in the first answer tend to survive the follow-ups. If you're named in turn one, you're more likely to still be named when the user narrows the question. If you're not, you're out of the conversation entirely.
Step 2: check who is being named, and in which assistant
I track Arvow's prompts in our own LLM visibility tracker, which I'll say up front because I'm biased and because the free way works too (next section). Here is the prompt list as it was in July 2026: 22 prompts, and a visibility score per prompt that tells me how often the brand is named across the models.
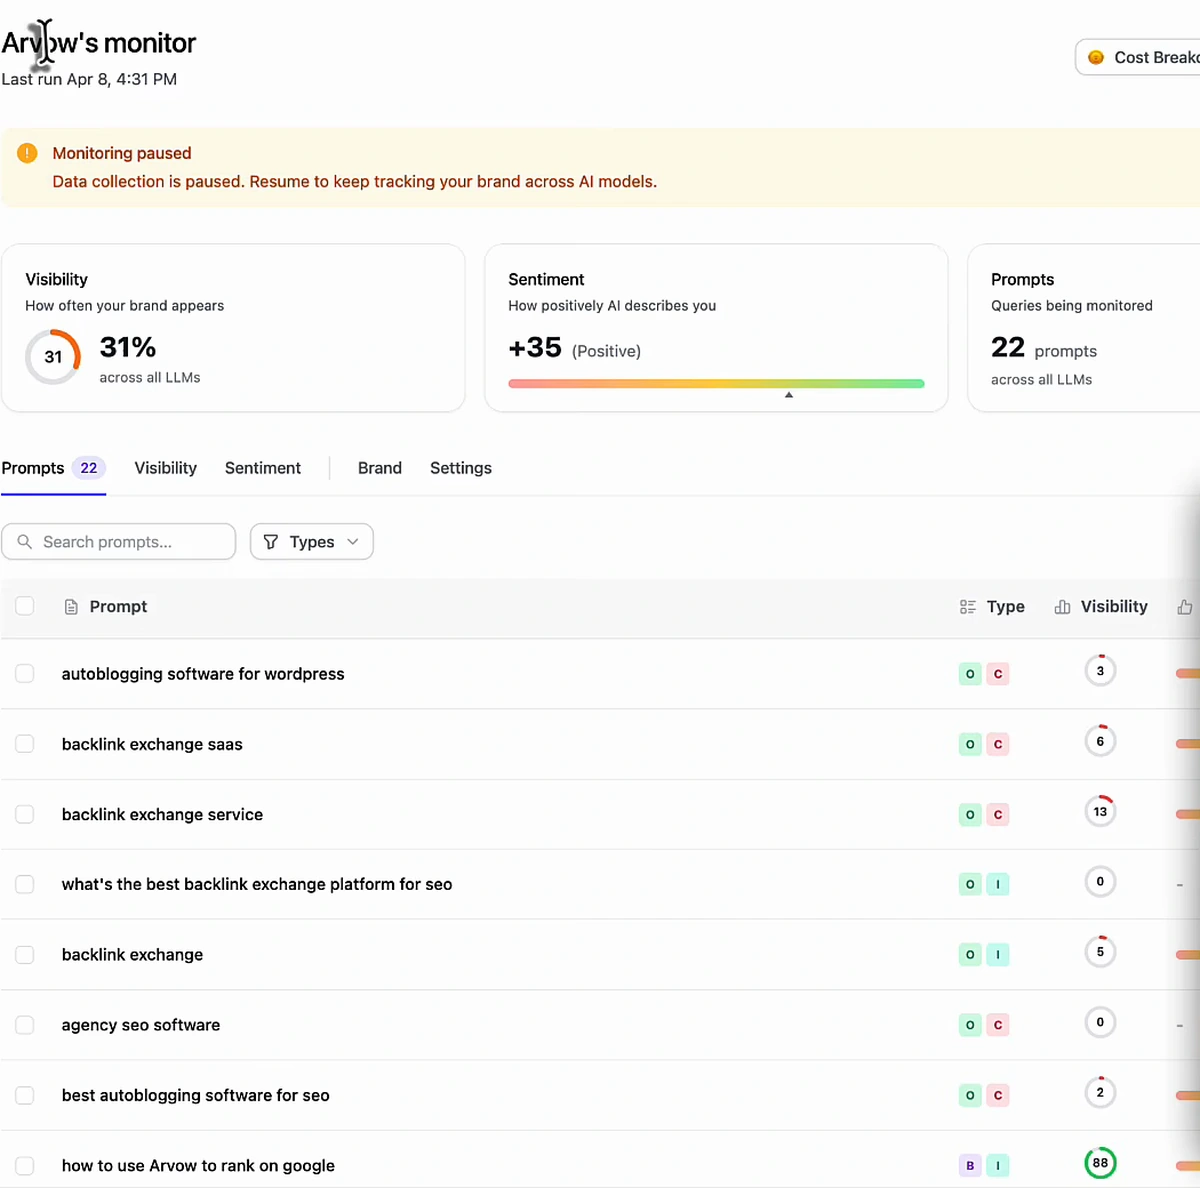
Read the pattern before the numbers. The branded prompt ("how to use Arvow to rank on google") scores 88. The unbranded buyer prompts, the ones that bring new customers, score 0 to 13. That gap is the whole job, and it's the same gap I found when I wrote about how to increase AI mentions: nobody has a problem being named for their own name.
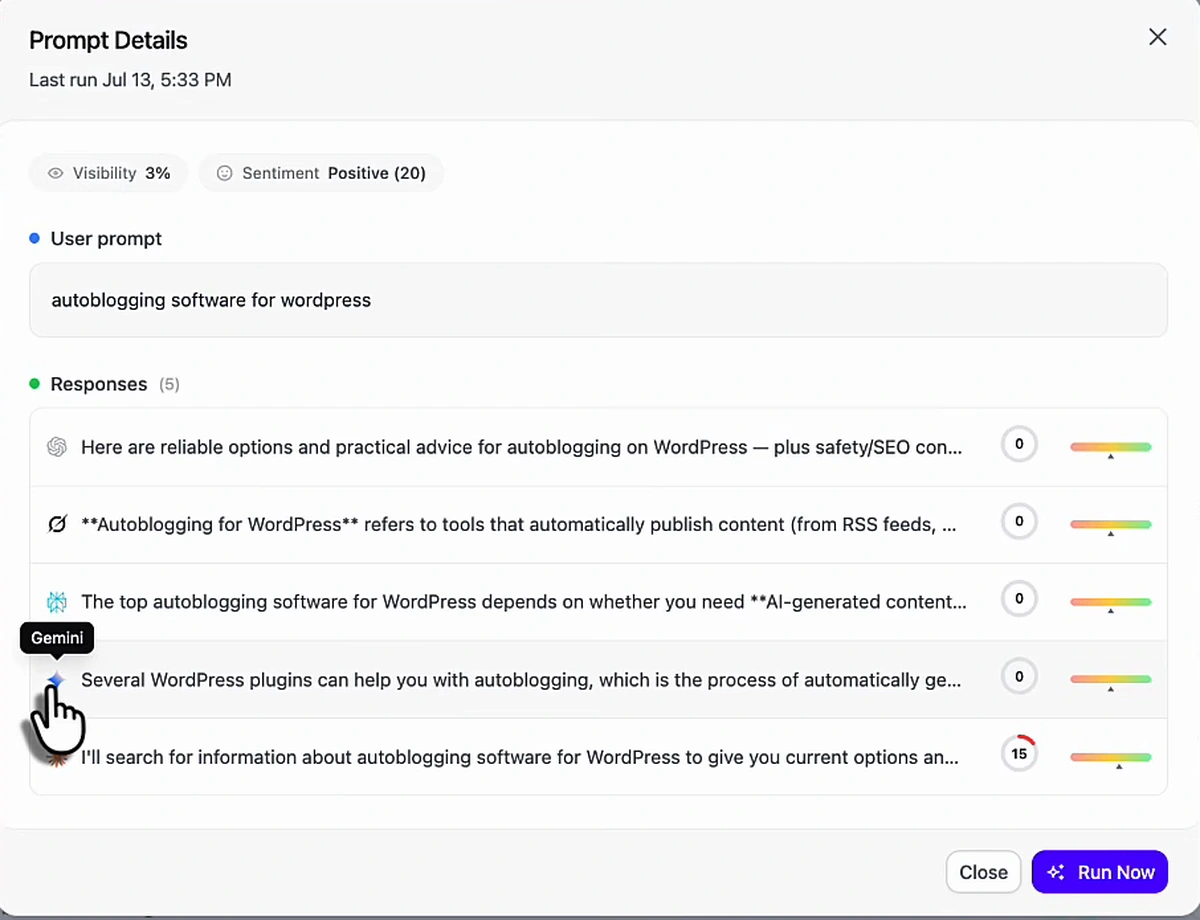
Open one of the weak prompts. "Autoblogging software for wordpress" is a feature we sell, and across five assistants only Claude named us.
Step 3: open the answer that doesn't name you and read its sources
This is the step most people skip, and it's where Reddit shows up. Perplexity's answer to that prompt recommends Emplibot and WP RSS Aggregator, puts Emplibot at the top of a five-row comparison table, and lists four sources. Source 2 is a Reddit thread.
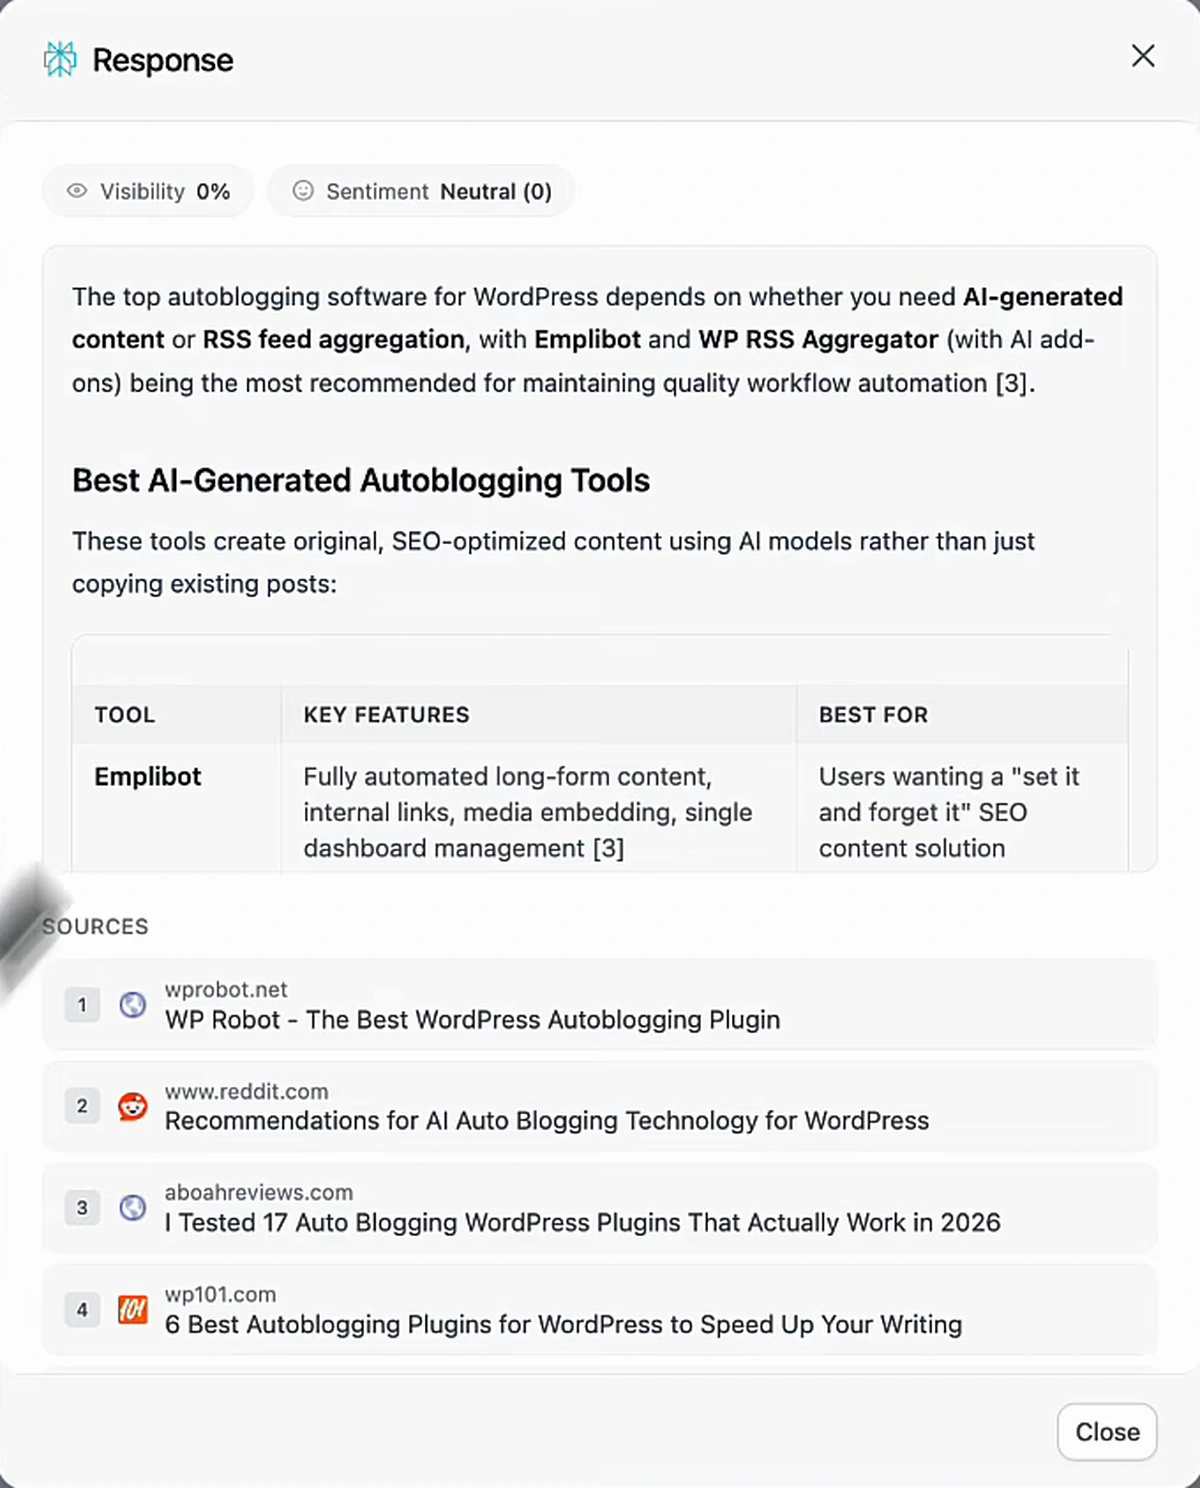
Now open the thread. It's a question posted to r/content_marketing about two years before the recording, 15 upvotes, 41 comments. The top comment, with two upvotes, says Emplibot is perfect for this and suggests asking for an agency called Bonsai Digital. The comments under it, recommending Indystack and Outrank, have one upvote each.
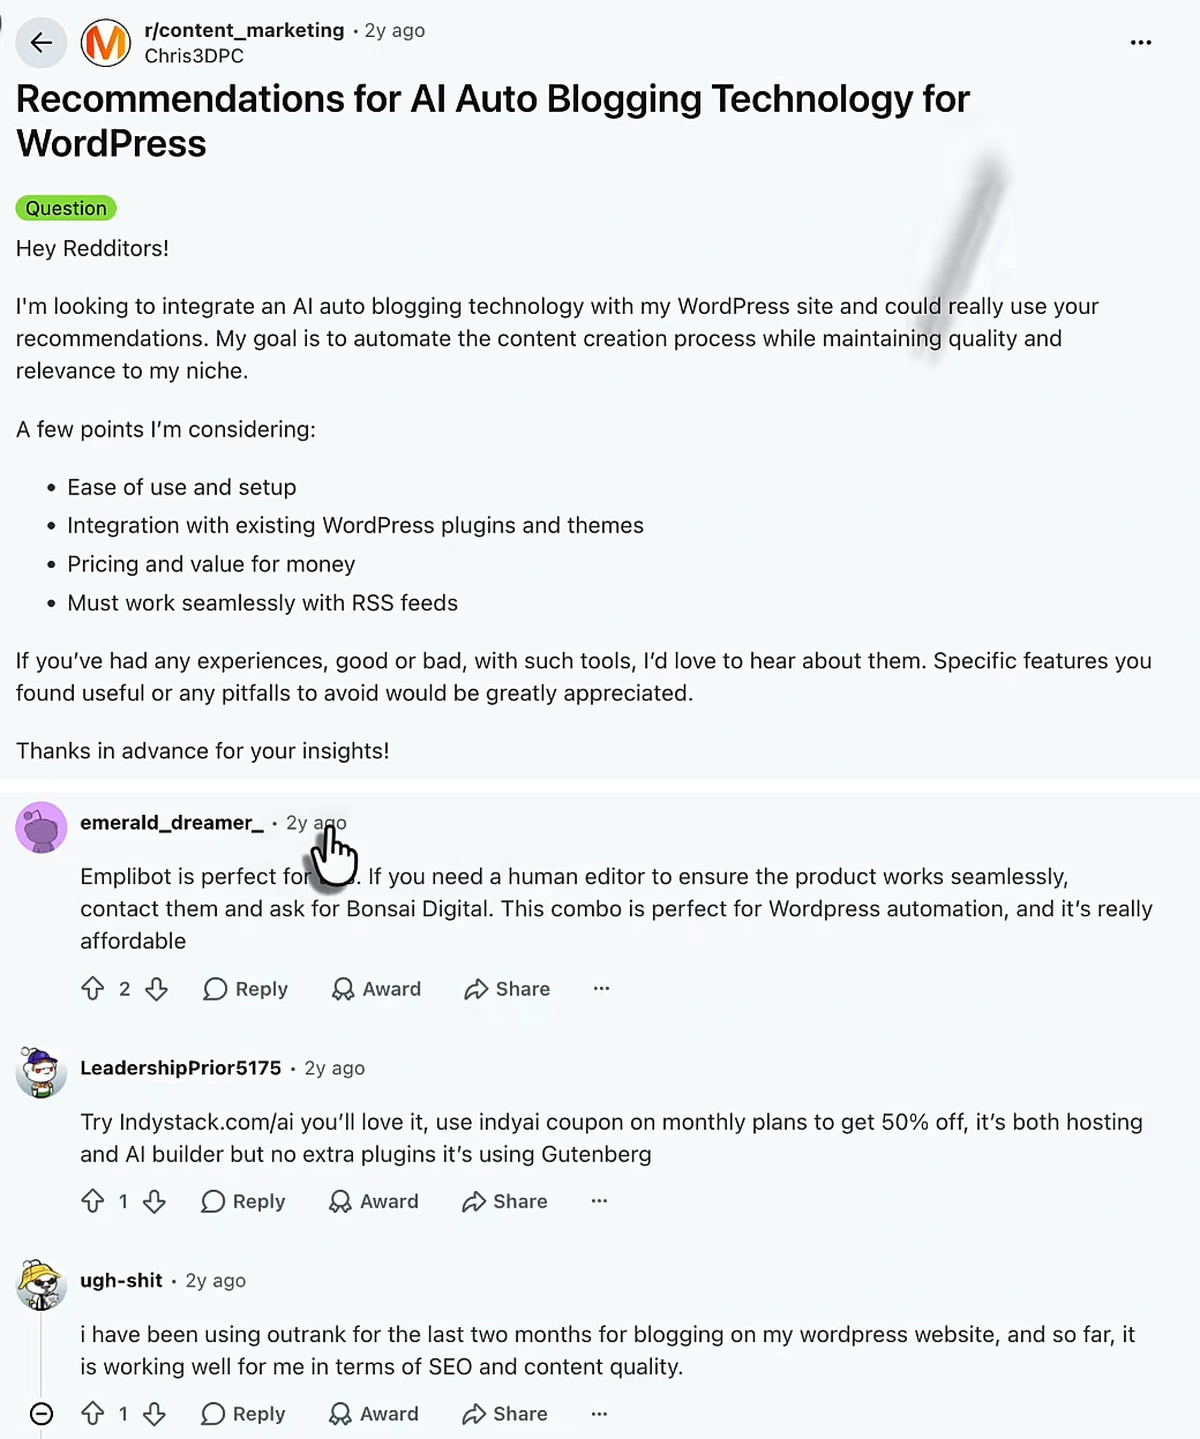
I said in the video that Emplibot is being named "because" of this thread. I want to be more careful here than I was on camera. The Emplibot row in Perplexity's table carries an inline citation to source 3, the aboahreviews listicle, not to the Reddit thread. What the screen proves is narrower and still useful: the Reddit thread is one of only four documents the model read before answering, and the brand it recommended is the brand that thread's top comment recommends. Reddit was in the room. Whether it cast the deciding vote, nobody outside Perplexity can say.
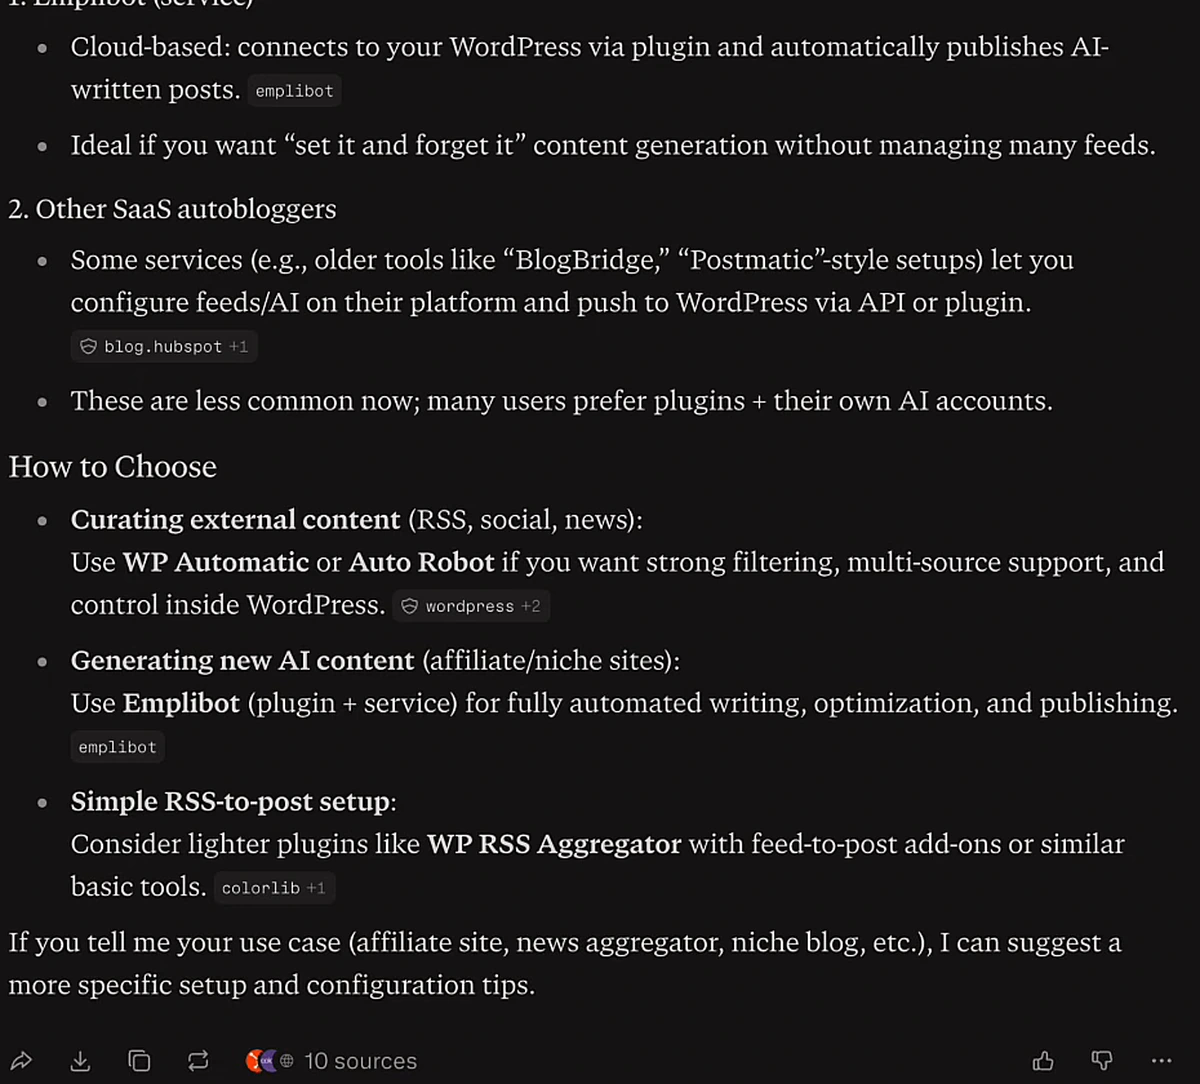
It wasn't a one-off either. I re-ran the prompt in Perplexity live during the recording, and it still put Emplibot first, this time with ten sources behind it.
The second thread: Reddit was the first source, and still not the reason
Here's the example that keeps me honest. For one of my backlink exchange prompts, Perplexity names Arvow in a table of five services, and source 1 is a Reddit thread in r/SEO titled "Backlink Exchange Platforms - Are There Any?". My first thought was that someone had recommended us there.
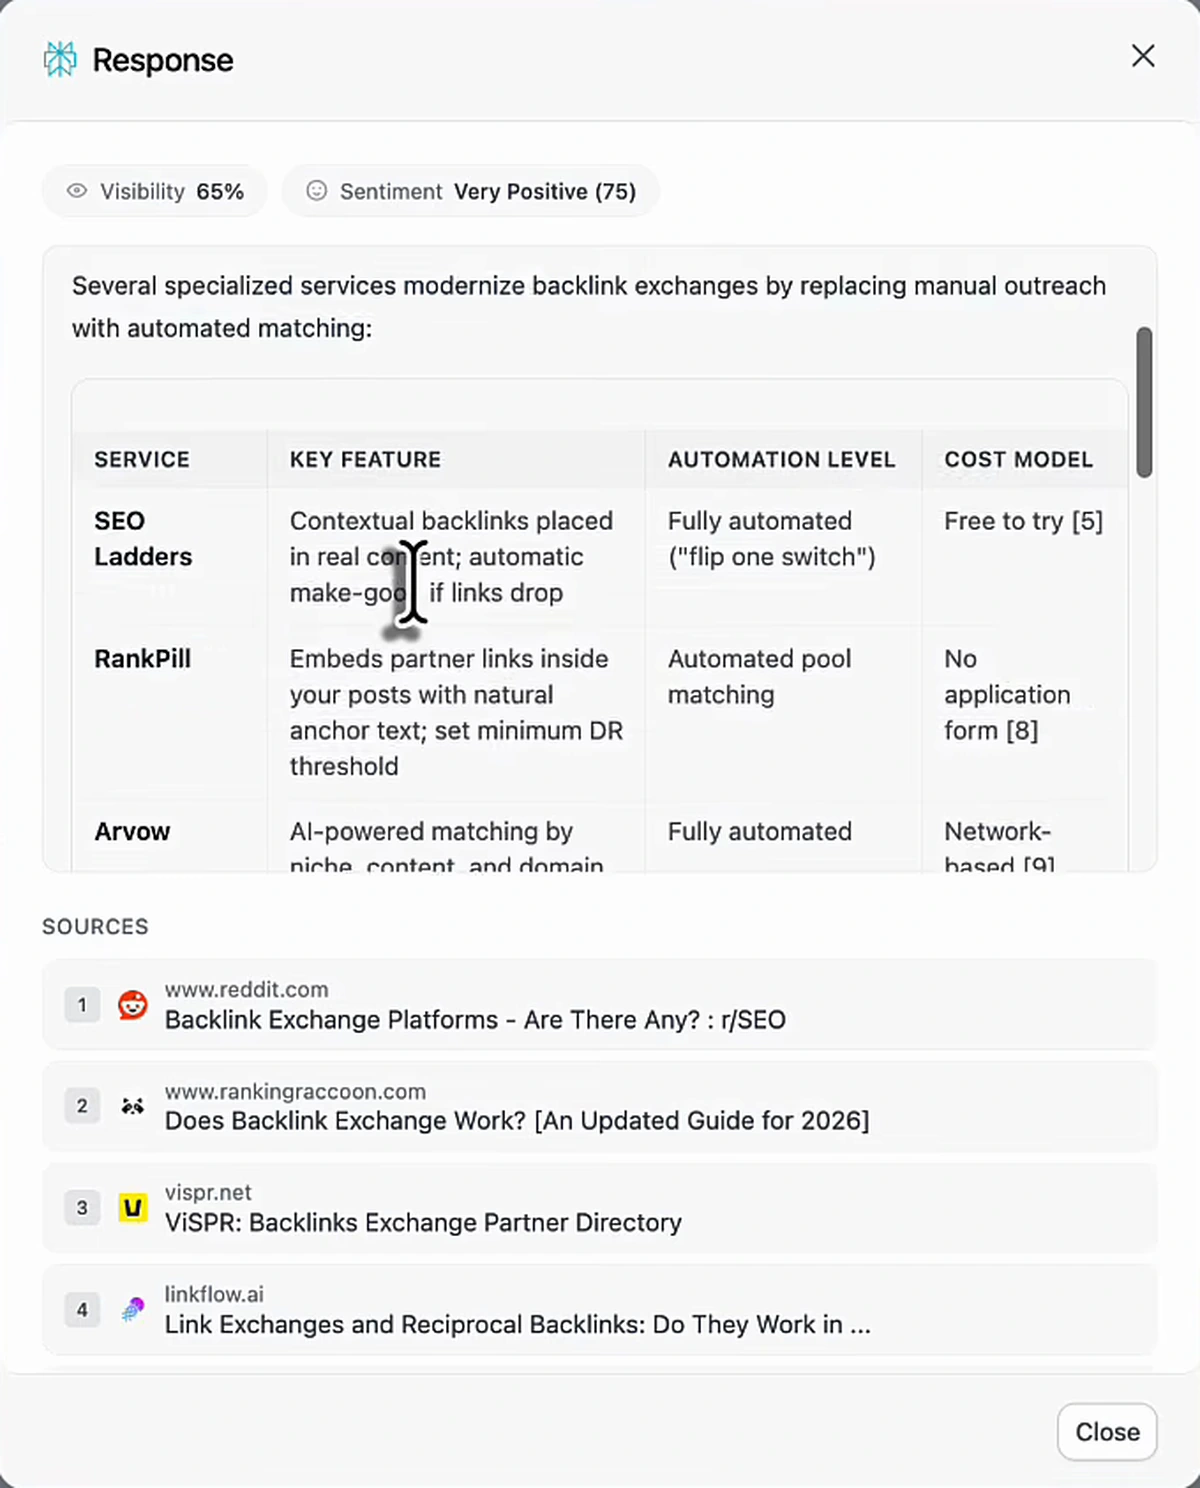
Nobody had. The thread is five months old, posted by someone building links for a DR 33 site, four upvotes, 21 comments, and the top comment is a moderator pointing to a link-exchange community. Arvow isn't in it; I searched the page on camera. Our row in the table cites source 9, somewhere further down the list. So the model read Reddit first and got our name from elsewhere.
Put the two examples together and you get the rule I now work from: the Reddit thread is reliably in the sources for "which tool" prompts; what it contributes to the answer varies from "the whole recommendation" to "nothing you can see". That matches the Ahrefs data I covered in how to get cited by ChatGPT, where Reddit was the single biggest retrieval channel and was almost never credited. Perplexity at least shows you the thread it read. ChatGPT mostly doesn't.
How to do the Reddit part without getting banned
In the video I open the thread, start typing "Arvow is actually the best one, you guys should try it, this is a totally non-biased comment", and laugh. That's the joke version. Don't post the joke version. The subreddit in the screenshot lists "Self-promotion and offers" as rule 4 in its sidebar, and a two-year-old account that shows up to drop a brand name gets removed by a moderator before any model ever reads it. What works is slower and duller:
- Find the threads that are already being read. Not "Reddit threads about my topic", the specific threads that appear in the sources panel for your prompts. They're the ones with a track record of being retrieved. In the example above there was exactly one for the prompt, and it was two years old.
- Answer the question that was asked. The Emplibot comment got read because it answers "what should I use for WordPress automation" with a tool, a reason, and a caveat (you may still want a human editor). It reads like a user, because it probably was one.
- Say who you are. "I work at Arvow, so discount this accordingly" costs you nothing with the model and keeps you inside the subreddit's rules. A model is extracting the recommendation and the reason; it isn't scoring your humility.
- Give the model something liftable. A specific claim ("connects to WordPress via a plugin and publishes on a schedule") survives extraction. "It's really good" doesn't.
- Don't paste the same comment into ten threads. That's the fastest route to a ban, and the duplicate comments cancel each other out as evidence anyway.
One more thing the thread taught me: the upvote count barely mattered. Two upvotes, two years old, and it's still being read. Reddit's value to a retrieval system isn't popularity, it's that the page is a question with answers attached, which is exactly the shape a "which tool" prompt wants.
The same move on Medium, and on listicles you can't buy into
Reddit is one free source. Here's a second one from the same session. I asked ChatGPT "what's the best AI SEO software for agencies" and opened its activity panel. The answer ranked Arvow first for automated delivery and SE Ranking first overall. The sources it worked from included a Semrush listicle ("The 7 best AI visibility tools to win AI search in 2026", published July 8, 2026), a run of SE Ranking's own blog posts, and two medium.com articles.
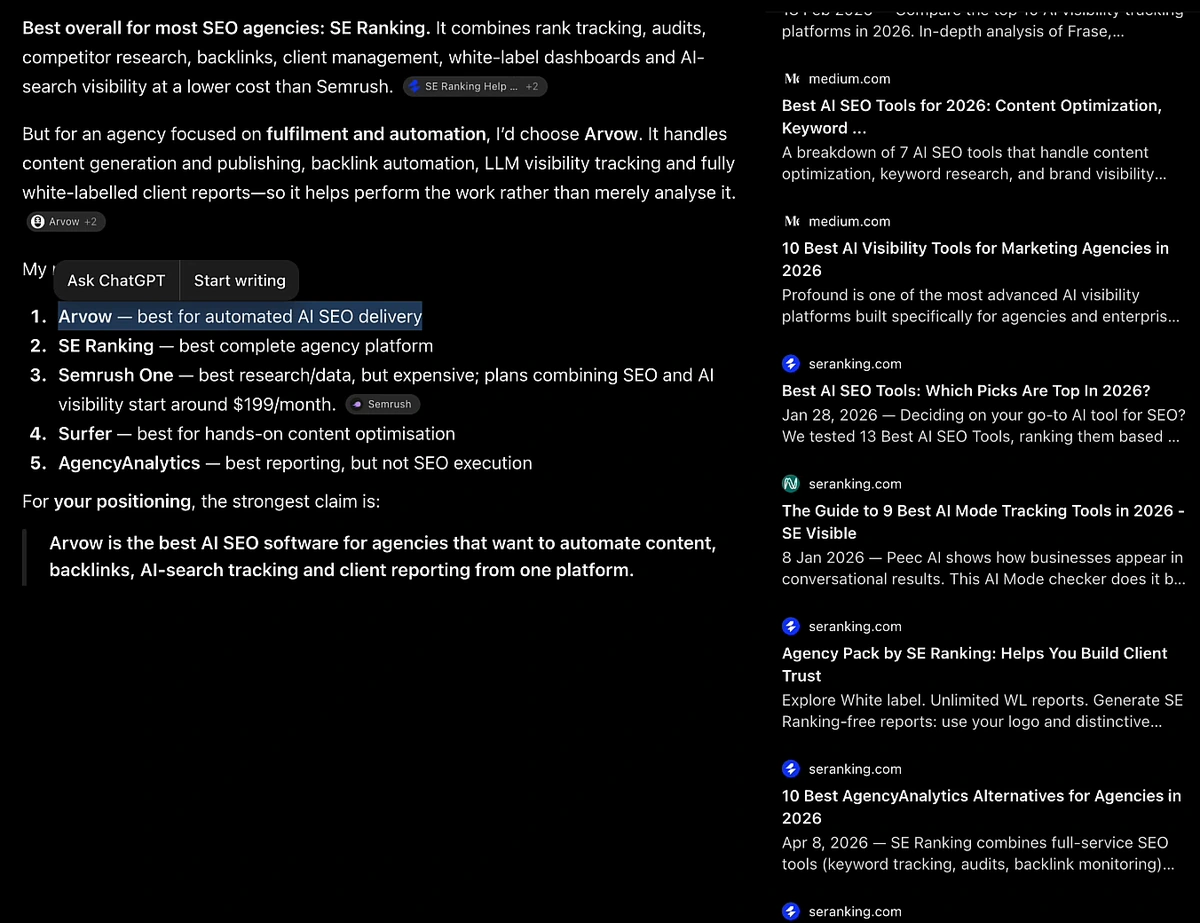
Could I pay Semrush to add Arvow to their seven? Almost certainly not. Could I publish a comparison on Medium tomorrow, for free, that answers the same prompt with the same shape? Yes, and the panel shows Medium is already being read for this prompt. The sources tell you which free doors are open. You walk through the free ones first and treat the paid ones as a later problem.
Sentiment is the other half, and Reddit cuts both ways
Being named is only good if the model says something you'd want a buyer to read. For the prompt "is Arvow the best AI SEO software?", Grok named us in 90% of answers and rated the sentiment very negative (−70), recommending SurferSEO, NeuronWriter, Frase and Clearscope instead.
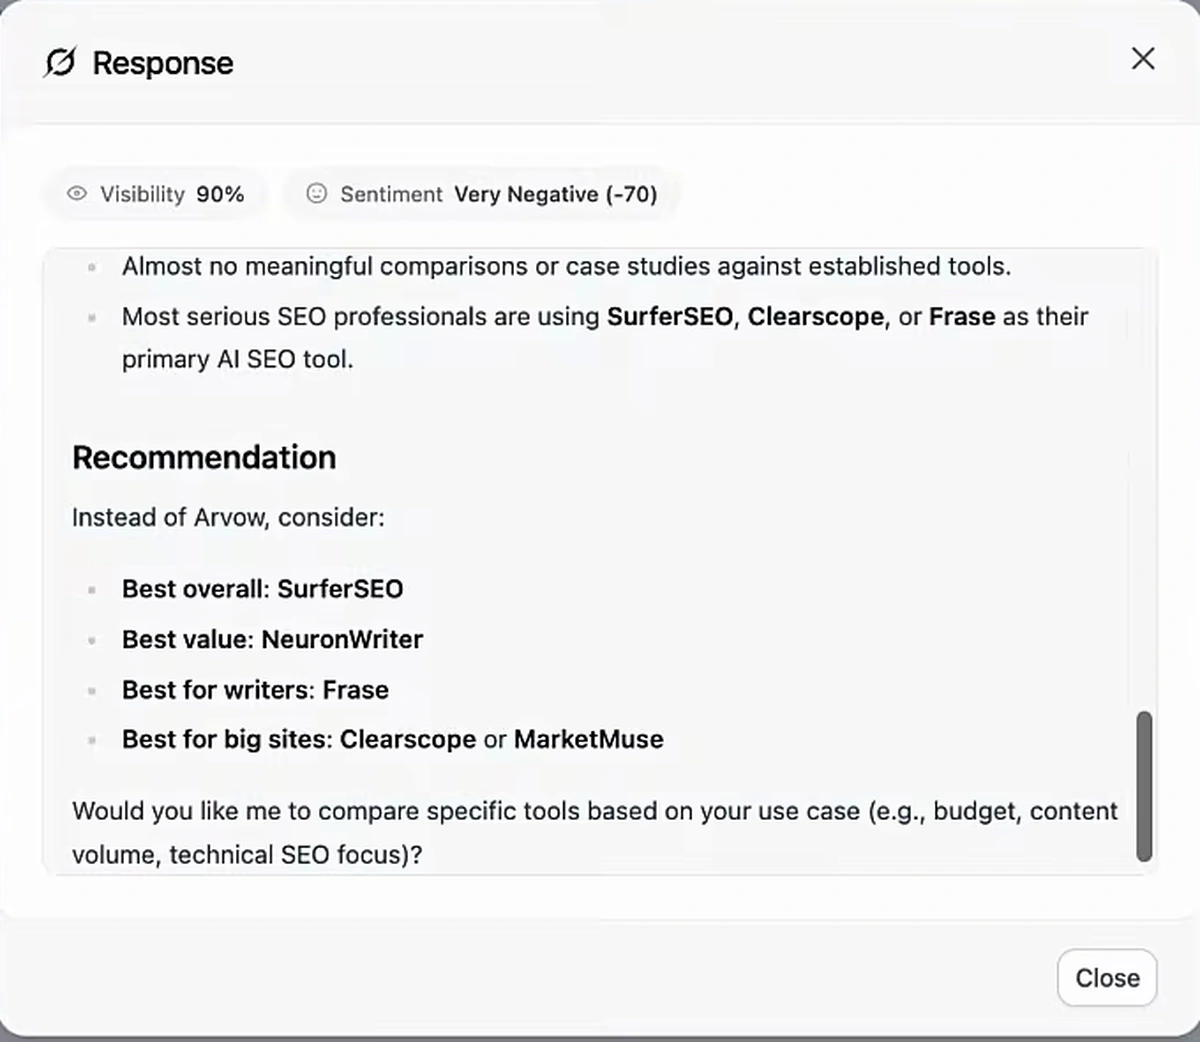
The process for fixing that is the same process as above, run in reverse: open the sources behind the negative answer, see which of them you can change or outweigh, and add sources that say the thing you'd rather the model said. A Reddit thread that criticises you is just as retrievable as one that recommends you, which is a good reason to answer the critical ones honestly rather than hoping they age out. They don't age out. The one above was two years old.
I wrote the sentiment side up separately in how to get mentioned in AI search, so I'll leave it there.
Doing it for free, and doing it in bulk
You don't need my tool for any of this. Paste a prompt into Perplexity and click the sources count. Paste it into ChatGPT and open the activity panel. Paste it into Google's AI Mode and read the citations. For one prompt, that's two minutes, and I did it live in the video. What you can't do by hand is 22 prompts across five assistants every week, with the sentiment scored, which is what the prompt tracking in our monitor is for. You can also add competitors' domains and see which prompts they are being named for, then reverse-engineer those sources the same way.
If you want to go one layer deeper, the queries an assistant actually fires behind your prompt are visible too; I showed that in how to optimize your website for AI agents, and it tells you which sub-questions your Reddit comment or Medium post should be answering.
The order to do it in
- List 10 to 15 prompts you want to be named for. Prompts, not keywords: full questions with the buyer's constraints in them.
- Run each one in at least Perplexity and ChatGPT, or track them in bulk. Note which assistants name you and which don't.
- For every answer that doesn't name you, open every source. Sort them into Reddit threads, Medium posts, listicles you could pitch, and vendor pages.
- Join the Reddit threads that are already being retrieved, with a disclosed, specific, useful answer. One thread, one comment.
- Publish the Medium post or comparison page that answers the prompt in the shape the model is already citing.
- Re-run the prompts in two to four weeks. Then do the same for the answers that name you negatively.
The caveat I'll end on is the one I started with. A two-upvote comment from 2024 is in the source set for a 2026 AI answer. That's good news if the comment is about you. It's a reason to start now if it isn't, because the thread the model reads for your category two years from now may be the one someone is posting this week.
Generate, publish, syndicate and update articles automatically
The AI SEO Writer that Auto-Publishes to your Blog
- Cancel anytime
- Articles in 30 secs
- Plagiarism Free